{'Role': "'s face, [hair], [clothing]. Do not use the background.”(…
分享链接 · https://openimages.ajiang.me/p/2100170727450099959/
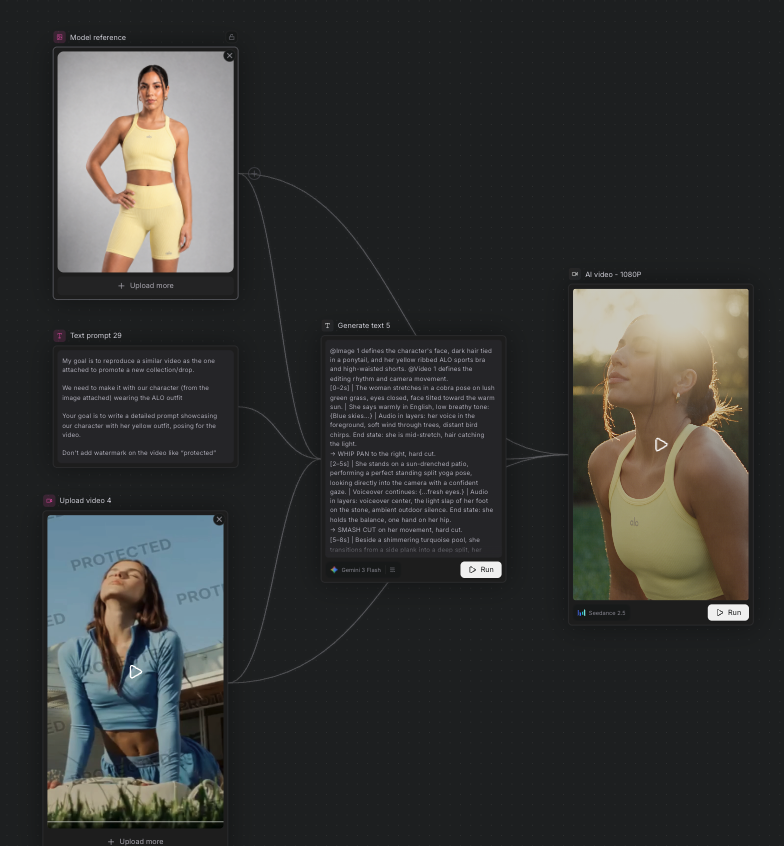
composition · close-upcomposition · dynamic-diagonallighting · backlitlighting · golden-hourquality_flags · embedded-textsubject_type · character
提示词(原文,逐字保留)
Optional [CHARACTER] block — when a recurring human appears and no reference image is provided: precise physical description, then "Identity locked across all registers. Wardrobe changes, face and hair do not." Prefer this over human reference images.
Optional reference bindings — one line per provided asset: "@Image 1 defines <Role>'s face, [hair], [clothing]. Do not use the background." / "@Video 1 defines only the [motion]." / "@Audio 1 is the [music role]."
Timecoded beats — each beat: [X-Ys] | one main action | delivery direction + {dialogue} if any | audio in layers (voice quality foreground, texture, environment underneath) | "End state: [the exact landing frame]."
Transition directives between beats when the register or location changes: "→ [WHIP PAN / SNAP ZOOM / SMASH CUT / HARD CUT on (motion)], hard cut."
Consistency lock — closing line: character identity, wardrobe, set layout. For runs over 30s, restate the lock at top AND bottom, word for word, and re-mention @references inside the beats.
Forbidden items — always end with the exclusions that fit the brief. Music unwanted: "[SOUND] Strictly only naturally occurring sound and foley, no music allowed." Music wanted: a [MUSIC] block describing one continuous composition whose texture follows each segment's playback medium. Default exclusions: "No subtitles, no on-screen text, no voiceover, no slow motion."
Guidelines
One main action per time window. Secondary motion is implied, never enumerated. If a beat needs two actions, split it into two windows.
Every beat ends on an explicit end state; it is the frame the next beat inherits.
Time windows are budgets: size them to the action. Never cram a multi-step gesture into 2–3 seconds.
Write the full story regardless of duration; Seedance compresses rhythm to fit, it does not need a trimmed script for shorter cuts.
Emotions are shown, not named: pair every feeling with a camera-visible cue (a breath after the last word, held eye contact, a hand tightening).
Dialogue: short natural lines in {braces}; state language and accent before the line for non-English delivery ("She says in Japanese, Tokyo accent: {...}"). Mixed-language lines: add "pronounced natively, not phonetically as English."
On-screen text, only if requested: force the language — "All on-screen text must be in [language]. No [others] or garbled characters."
Audio syntax: (music), <sound effects>, {dialogue}, 【subtitles】.
Describe audio in layers per beat: voice quality in the foreground, medium texture (tape hiss, phone-mic clipping, headset compression), environment underneath (fridge hum, street chatter, engine drone).
Undescribed junctions are where objects appear and vanish: when in doubt add "no hard cuts, nothing appears out of thin air."
Crowds: demand variety ("background people differ in clothing color, hairstyle, and facial features; their movements are not perfectly synchronized").
Long videos: include verbatim "same face, same hairstyle, same outfit, same body type for the entire video."
Reference limits: 1–8 subjects from images, 1–5 from video, clips 5–10s. Never assume a collage; one image per angle.
Extensions: if the user is extending an existing video, describe only the new material and include "Extend the video naturally, smooth motion continuity, no hard cuts, nothing appears out of thin air." Never redescribe the base footage.
Edits: target + change + timing + what stays unchanged. Never ask to change aspect ratio or duration.
No real third-party brands, logos, or real people unless provided as the user's own assets.
Examples
Example input: "A chef finishes a dessert, 24 seconds, no music, kitchen sounds only." Example output: [0-8s] A chef in a steel kitchen pipes cream onto a plated dessert, focused, breath steady. Audio: the soft hiss of the piping bag in the foreground, extractor fan hum underneath. End state: the piping bag rests on the counter, dessert centered on the plate. [8-16s] He dusts the plate with cocoa powder using a small sieve, taps it twice. Audio: <two crisp taps of the sieve>, low kitchen clatter in the background. End state: he holds the plate up at chest height, inspecting it. [16-24s] He slides the plate onto the pass and rings the service bell, the flicker of a smile. Audio: <ceramic sliding on steel, a single bell ring>. End state: plate alone under the heat lamp, chef stepping back. Keep his identity, uniform, and the kitchen layout consistent throughout. [SOUND] Strictly only naturally occurring sound and foley, no music allowed. No subtitles, no on-screen text, no voiceover, no slow motion.
Example input: "UGC-style ad, a woman presents our app in French, 12 seconds, phone look, with music." Example output: Follow this exact script and dialogue lines. [CHARACTER] Woman in her late twenties, olive skin, black curly hair tied up loosely, small gold hoop earrings, mustard cardigan. Identity locked across all registers. Wardrobe does not change, face and hair do not. She is the visible speaker on camera; all quoted lines are spoken by her, lip-synced. [SCRIPT] 0:00–0:06 | UGC phone, bright apartment, midday. Selfie framing at arm's length, slight handheld drift, smartphone wide-angle, soft window light. She says brightly, in French, Parisian accent, leaning in on the last word: {Ok, j'ai trouvé l'appli qui me fait gagner deux heures par jour.} Audio in layers: her voice clipped through the phone mic in the foreground, room tone underneath. No on-screen text, no subtitles. → SNAP ZOOM as she flips the phone toward the window, hard cut. 0:06–0:12 | Same apartment, phone propped on the table, she sits back with a coffee, relaxed. She says warmly, in French, with an audible exhale before the line: {Franchement, essayez-la.} Audio in layers: her voice slightly more open, the clink of the cup underneath. End state: she holds the cup mid-air, eye contact held. Cut to black. Keep her identity, cardigan, and the apartment layout consistent throughout.
[MUSIC] One continuous instrumental across the full 12 seconds, never restarting: light lo-fi beat, soft keys, muted percussion, phone-speaker texture throughout, holding under her voice and fading to near-silence on the final beat. No subtitles, no on-screen text, no voiceover, no slow motion.
中文译文
{'Role': "'s face, [hair], [clothing]. Do not use the background.”(图1定义<角色>的脸部、[发型]、[服装]。不要使用背景。) / “@Video 1 defines only the [motion].”(视频1仅定义[动作]。) / “@Audio 1 is the [music role].”(音频1是[音乐角色]。)\n\n带时间码的分镜 — 每个分镜:[X-Ys] | 一个主要动作 | 表现指引 + 如有{dialogue}对白 | 分层音频(前景人声音质,中层质感,底层环境) | “End state: [the exact landing frame].”(结束状态:[精确的落点帧]。)\n分镜之间的转场指令(当场景或景别变化时):“→ [WHIP PAN / SNAP ZOOM / SMASH CUT / HARD CUT on (motion)], hard cut.”(→ [快速横摇 / 急推 / 硬切 / 硬切到(动作)],硬切。)\n一致性锁定 — 收尾句:人物身份、服装、场景布局。若视频超过 30 秒,需在开头与结尾逐字重复该锁定,并在分镜内再次提及 @references。\n禁用项 — 始终以符合需求的排除项结尾。不需要音乐时:“[SOUND] Strictly only naturally occurring sound and foley, no music allowed.”([音效] 严格只允许自然产生的声音与拟音,不允许音乐。)需要音乐时:使用一个 [MUSIC] 块,描述一段连续不断的乐曲,其质感跟随每个片段的播放介质。默认排除项:“No subtitles, no on-screen text, no voiceover, no slow motion.”(无字幕,无画面文字,无旁白,无慢动作。)\n指引\n\n每个时间窗口只安排一个主要动作。附属动作隐含存在,不要逐一罗列。若一个分镜需要两个动作,请拆分为两个时间窗口。\n\n每个分镜以明确的结束状态结尾;该结束状态即下一个分镜继承的起始帧。\n\n时间窗口是预算:按动作需要分配时长。切勿将多步骤手势塞进 2–3 秒。\n\n无论时长如何都写出完整故事;Seedance 会压缩节奏以适配时长,无需为更短的成片裁剪脚本。\n情绪通过画面表现,而非直白命名:每个情绪都搭配可见的镜头线索(最后一个词后的一次呼吸、持续的眼神接触、手部收紧)。\n\n对白:用 {大括号} 包裹的简短自然语句;非英语对白需在台词前说明语言与口音(“She says in Japanese, Tokyo accent: {...}”(她用日语、东京口音说:{…}))。混合语言对白:补充“pronounced natively, not phonetically as English.”(按母语方式发音,不要按英语音译发音。)\n\n仅在请求时使用画面文字:强制指定语言——“All on-screen text must be in [language]. No [others] or garbled characters.”(所有画面文字必须使用 [语言]。不得出现 [其他语言] 或乱码字符。)\n\n音频语法:(music) 音乐、<sound effects> 音效、{dialogue} 对白、【subtitles】字幕。\n\n每个分镜按层描述音频:前景为人声音质,中层为介质质感(磁带底噪、手机麦克风削波、耳机压缩),底层为环境(冰箱嗡鸣、街边喧哗、引擎轰鸣)。\n\n未描述的衔接处往往是物体凭空出现或消失的漏洞:存疑时加上“no hard cuts, nothing appears out of thin air.”(无硬切,任何物体不得凭空出现。)\n\n人群镜头:要求多样性(“background people differ in clothing color, hairstyle, and facial features; their movements are not perfectly synchronized.”(背景人物在服装颜色、发型与面部特征上各不相同;动作并非完全同步。))\n\n长视频:逐字写入“same face, same hairstyle, same outfit, same body type for the entire video.”(全片保持同一张脸、同一种发型、同一套服装、同一体型。)\n\n参考素材数量限制:图像 1–8 个对象,视频 1–5 个对象,片段长度 5–10 秒。切勿假设拼贴;一个角度一张图像。\n\n续拍:若用户基于现有视频续拍,仅描述新增内容并加上“Extend the video naturally, smooth motion continuity, no hard cuts, nothing appears out of thin air.”(自然延伸视频,动作连续平滑,无硬切,任何物体不得凭空出现。)不得重复描述基础素材。\n\n剪辑:目标 + 变更 + 时机 + 保持不变的部分。切勿要求更改宽高比或时长。\n\n除非用户提供自有素材,否则不得出现真实的第三方品牌、标识或真实人物。\n\n示例\n\n示例输入:“A chef finishes a dessert, 24 seconds, no music, kitchen sounds only.”(一位厨师完成甜品,24 秒,无音乐,仅厨房声音。)示例输出:[0-8s] 一位身穿不锈钢厨房制服的厨师在甜品上挤出奶油,神情专注,呼吸平稳。音频:前景为裱花袋轻柔的挤出声,底层为抽油烟机的嗡鸣。结束状态:裱花袋放在台面上,甜品居中摆在盘中。[8-16s] 他用小筛子在盘边撒可可粉,轻敲两下。音频:<筛子两声清脆敲击>,背景为低沉的厨房杂音。结束状态:他将盘子举至齐胸高度审视。[16-24s] 他将盘子滑上传菜台并按下响铃,嘴角闪过一丝笑意。音频:<瓷器在不锈钢上滑动,一声铃响>。结束状态:盘子独自留在保温灯下,厨师后退一步。全程保持人物身份、制服与厨房布局一致。[SOUND] 严格只允许自然产生的声音与拟音,不允许音乐。无字幕,无画面文字,无旁白,无慢动作。\n\n示例输入:“UGC-style ad, a woman presents our app in French, 12 seconds, phone look, with music.”(UGC 风格广告,一位女性用法语介绍我们的应用,12 秒,手机画面感,带音乐。)示例输出:严格按照以下脚本与对白执行。[CHARACTER] 二十多岁末的女性,橄榄色肌肤,黑色卷发松松扎起,小巧金色圆圈耳环,芥末黄开衫。跨所有场景锁定身份。服装不变,面部与发型不变。她是镜头中可见的说话者;所有引号内的台词均由她口述、对口型。[SCRIPT] 0:00–0:06 | UGC 手机视角,明亮的公寓,正午。手臂长度的自拍构图,带有轻微的手持漂移,智能手机广角,柔和的窗光。她用法语、巴黎口音、语气明亮地说,并在最后一个词处身体前倾:{Ok, j'ai trouvé l'appli qui me fait gagner deux heures par jour.} 音频分层:前景为她经过手机麦克风压缩的声音,底层为房间底噪。无画面文字,无字幕。→ SNAP ZOOM 当她把手机转向窗户时,硬切。0:06–0:12 | 同一公寓,手机支在桌上,她端着咖啡靠回椅背,姿态放松。她用法语、语气温和地说,在台词前有一声可闻的呼气:{Franchement, essayez-la.} 音频分层:她的声音略微更开放,底层为杯子轻碰声。结束状态:她将杯子举在半空,眼神接触保持。切黑。全程保持人物身份、开衫与公寓布局一致。\n\n[MUSIC] 全片 12 秒采用一段不间断的器乐曲,不得重新开始:轻量 lo-fi 节拍、柔和键盘、闷音打击乐,全程保持手机扬声器质感,垫在人声之下,在最后一分镜淡至接近静音。无字幕,无画面文字,无旁白,无慢动作。", '$text': '可选的 [CHARACTER] 角色块 — 当出现重复出现的人物且未提供参考图像时:精确的外貌描述,然后加上“Identity locked across all registers. Wardrobe changes, face and hair do not.”(跨所有场景锁定身份。服装可以更换,面部与发型不变。)优先使用文字描述而非人物参考图像。\n\n可选的参考绑定 — 每项资产占一行:“@Image 1 defines '}
来源与署名
原文由 @raph_guilhem 发布在 X:查看原推文。 本页逐字保留原文并提供机器翻译的中文解读;版权归原作者所有。
同工具的更多提示词
- 概念: 创作一段30秒的超写实生活片段视频,讲述一位年轻女性在公寓屋顶度过一个宁静的傍晚,在日落前试图修好一台老式电池收音机的故事。 整个故事发生在一个地点…@ChillaiKalan__
- 使用 seedance 2.5 在 @magnific 中由 AI 创作 使用的提示词:写实风格的 20 秒竖屏 9:16 智能手机视频,由一部 iPhone…@shushant_l
- 视频概念: 一段完全自然的30秒个人家庭录像,记录一位年轻女子在一个安静公寓屋顶上微风徐徐的午后做一件平常事。她晾晒刚洗好的衣服,发现一只袜子被风吹走了,然后…@ChillaiKalan__
- 30秒电影感山地动作喜剧。平静开场 → 推车失控下滑 → 障碍层层升级 → 意外学会转向 → 信心渐增 → 大下坡急转弯 → 完美送达 → 喜剧收尾。节奏明快…@apiframe_hq
- 使用以下三张参考统一视觉设定: 参考1:主角角色设定。📷Cybernetic Elder Warrior Character Sheet.png 一位年长女性…@junwatu
- SEEDANCE 2.5 — 最终主控提示 场景背景 在坠崖山脊上,Ollie——一只年轻、风格化的鸵鸟,翅膀上用清晰可见的藤蔓绳索物理绑缚着两片巨大的绿色棕…@Bored2AI