第二步:先图后视频。永远如此。
分享链接 · https://openimages.ajiang.me/p/2078145909276475401/
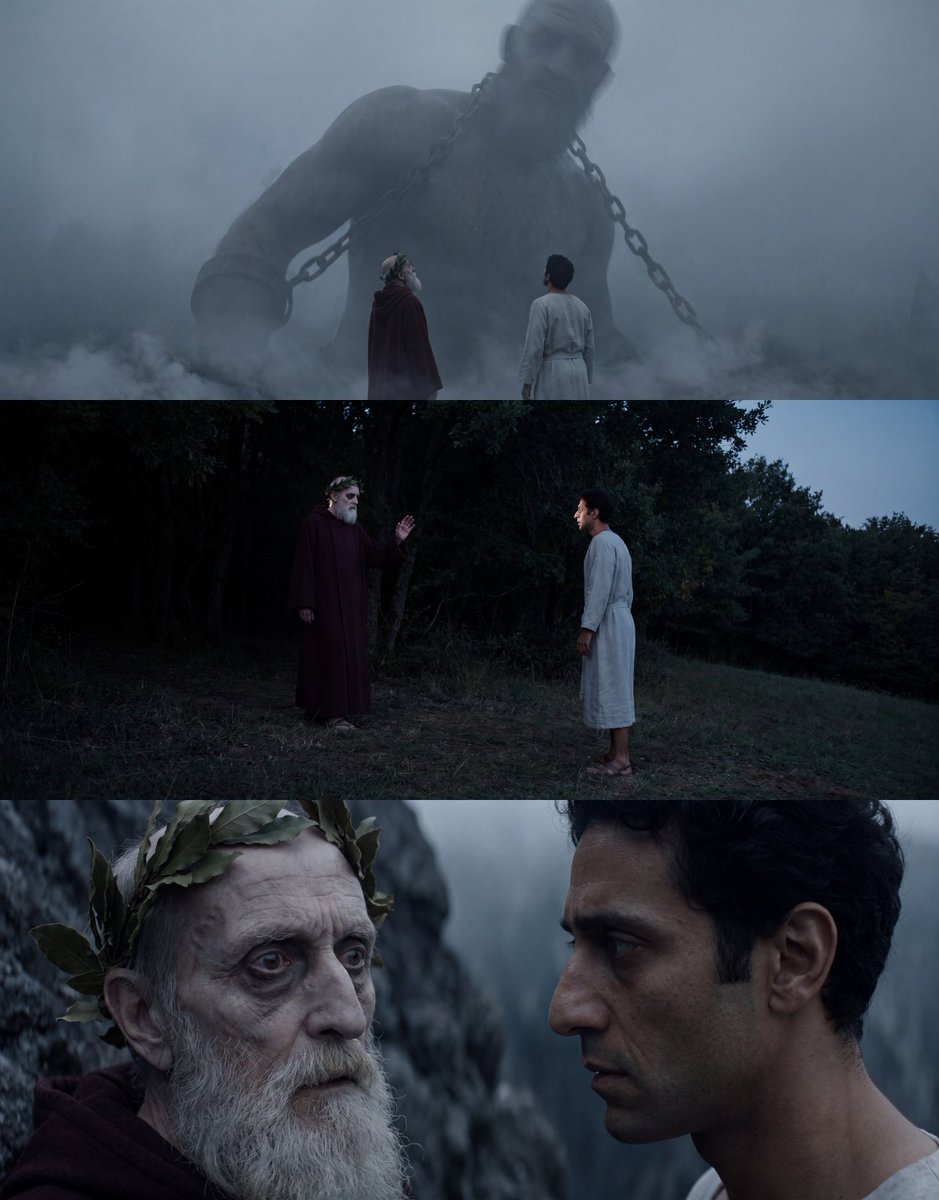
color_palette · cool-tonescomposition · multi-panelcomposition · wide-shothuman_attributes · facial-hairlighting · volumetric-lightmood · dramatic
提示词(原文,逐字保留)
STEP 2: Image before video. Always.
I rarely go straight from text to video. Every single video clip started as a still image first.
The image locks composition, lighting, character placement, and environment. Then the video model animates what already exists rather than inventing everything from scratch.
My pipeline: Text prompt > Still image (Nano Banana Pro, 4K, 21:9) > Video (Seedance 2.0, 1080p, 15s max)
中文译文
第二步:先图后视频。永远如此。
我很少直接从文字生成视频。每一段视频片段都先从一张静态图像开始。
图像确定构图、光线、角色位置和场景环境。然后视频模型在此基础上进行动画化,而不是从零开始凭空创造。
我的工作流程:文字提示 > 静态图像(Nano Banana Pro,4K,21:9)> 视频(Seedance 2.0,1080p,最长 15 秒)
来源与署名
原文由 @maxescu 发布在 X:查看原推文。 本页逐字保留原文并提供机器翻译的中文解读;版权归原作者所有。
同工具的更多提示词
- 使用 Gemini Nano Banana 2 在 @GeminiApp 上创建 提示词 👇 一位自信的男士居中站立于一张正面直对的中景肖像中,他平稳的肩膀与…@pictsbyai
- { "type": "image_prompt", "version": "1.0", "content": { "subject": { "descript…@KeorUnreal
- 对 $ dish 执行以下操作:函数 DrawDishHoudiniFluid(输入 dish) 输入变量:[INSERT DISH] 系统指令:生成一张超写…@Gdgtify
- 你最喜欢哪些名人的姿势和表情? Sabrina Carpenter、Sydney Sweeney、Jennifer Lopez 和 Kylie Jenner…@Ankit_patel211
- 超写实的黑白影棚人像:一位自信的运动型男子正面直视镜头,双臂交叉于胸前。 人物占据画面垂直方向的约 75–80%,裁切范围从大腿中部向上。他身穿一件剪裁合体的…@kingofdairyque
- 一张令人惊艳的专业影棚时尚编辑风格的高清照片,主角为[NAME],呈现出自信、富有表现力的中景半身像。她直视镜头,露出含蓄而大胆的微笑。她那长长的波浪状金发梳…@Giulia_4i