我注意到 AI 图像模型处理提示词的方式有一些特点:基于 CLIP 的文本编码器会将你的文字切分成离散的 token(词元)。当你的提…
分享链接 · https://openimages.ajiang.me/p/2040211676239396968/
color_palette · white-minimalcomposition · centeredquality_flags · typography-heavysubject_type · diagram-documentusage · presentationusage · social-post
提示词(原文,逐字保留)
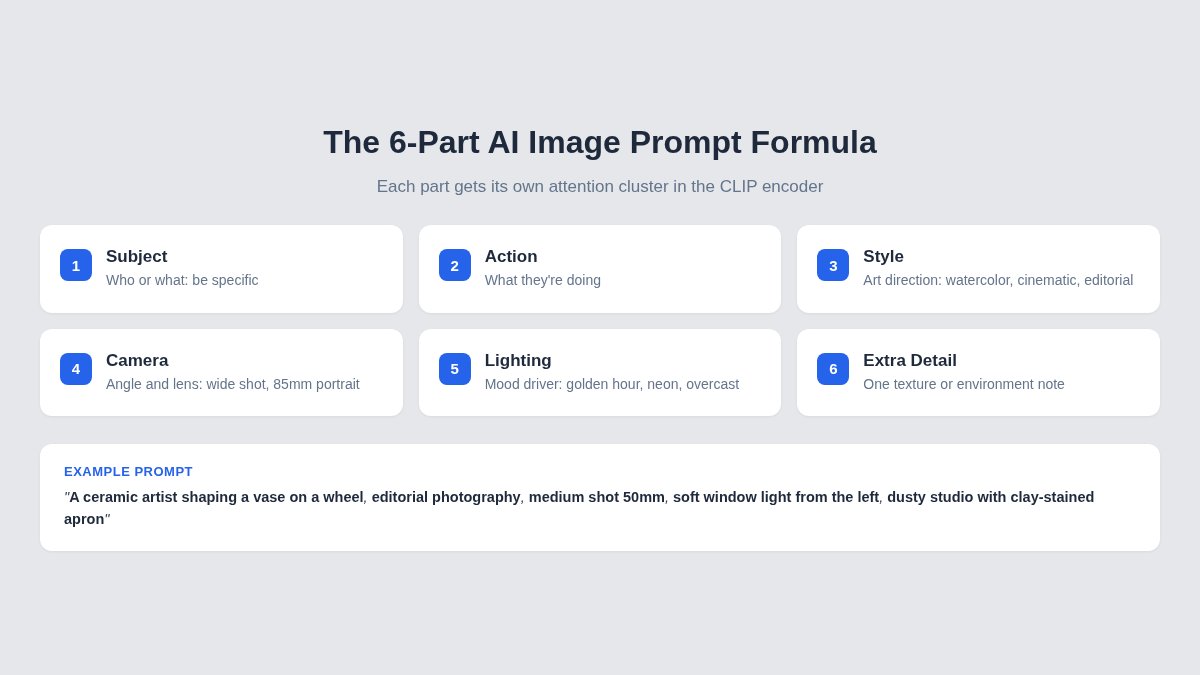
I noticed something about how AI image models process prompts: CLIP-based text encoders tokenize your words into discrete chunks. When your prompt is one long sentence, key details compete for the same attention weight. The model guesses what matters.
A structured prompt fixes that. Each concept gets its own attention cluster.
I've been using a 6-part formula and the results are noticeably sharper:
1- Subject: who or what (be specific)
2- Action: what they're doing
3- Style: art direction (watercolor, cinematic, editorial)
4- Camera: angle and lens (wide shot, 85mm portrait)
5- Lighting: mood driver (golden hour, neon, overcast)
6- Extra detail: one texture or environment note
Example: "A ceramic artist shaping a vase on a wheel, editorial photography style, medium shot 50mm, soft window light from the left, dusty studio with clay-stained apron"
Swap one part at a time to see what each controls.
#AIImages #PromptEngineering #AITips #GenerativeAI #CreativeAI
中文译文
我注意到 AI 图像模型处理提示词的方式有一些特点:基于 CLIP 的文本编码器会将你的文字切分成离散的 token(词元)。当你的提示词是一整句长句子时,关键细节会争夺相同的注意力权重,模型只能猜测哪些内容更重要。
而结构化的提示词可以解决这个问题——每个概念都会拥有独立的注意力聚类。
我一直在使用一个 6 部分公式,效果明显更清晰:
1- Subject(主体):是谁或是什么(要具体)
2- Action(动作):在做什么
3- Style(风格):艺术方向(watercolor 水彩、cinematic 电影感、editorial 编辑摄影)
4- Camera(镜头):角度与焦距(wide shot 广角、85mm portrait 85mm 人像)
5- Lighting(光线):情绪驱动(golden hour 黄金时刻、neon 霓虹、overcast 阴天)
6- Extra detail(额外细节):一个质感或环境描述
示例:"A ceramic artist shaping a vase on a wheel, editorial photography style, medium shot 50mm, soft window light from the left, dusty studio with clay-stained apron"
每次只替换一个部分,就能看出每个要素控制的是什么。
#AIImages #PromptEngineering #AITips #GenerativeAI #CreativeAI
来源与署名
原文由 @FadyEid 发布在 X:查看原推文。 本页逐字保留原文并提供机器翻译的中文解读;版权归原作者所有。
同工具的更多提示词
- 三位古怪奇趣的女性,宽间距的眼睛,金色卷曲蓬松的头发,穿着宽大破旧的蒸汽朋克服饰,维多利亚式层叠穿搭,拼布外套,夸张的大礼帽和护目镜,脚踩不搭配的厚重笨重靴子…@Viper_Tattoo_
- 看着镜头,表情俏皮,双手比出胜利手势(V字), 肖像,身体面向镜头, 穿着白色带领衬衫,格纹蝴蝶结领带,藏青色格纹百褶迷你裙,裙子内侧略带白色, 站立,双膝跪…@BeautyVerse_Lab
- 展示中间发生了什么。使用多角度镜头 起始/结束 帧/输出 https://t.co/xkySvGDDKS@BrentLynch
- YouTuber MrBeast 装扮成剧集《The Amazing Digital Circus》中的 Caine https://t.co/A6SOPIN…@noah47440815510
- https://t.co/03IcaHtPrE@bhaidar
- 我应该铺设道路吗? 老实说……现在有多少人正在 ChatGPT 里敲出和这一模一样的问题?它给你的只会是一个泛泛而谈、毫无用处的答案。 ✅ 升级版提示词: 请…@briansearl